What Changes in Content Strategy When AI Engines Handle Discovery
Brands now need extractable answers and independent corroboration to earn AI citations.
Content strategy changes when AI engines handle discovery because the objective is no longer just to earn a ranking position. It is to supply passages that an engine can extract, trust, and cite. That shift calls for a different way to produce and share content, with answers that stand on their own, independent corroboration, and measures of how often the brand is seen before a click.
How AI engines have changed the discovery pipeline — and why it matters for content strategy
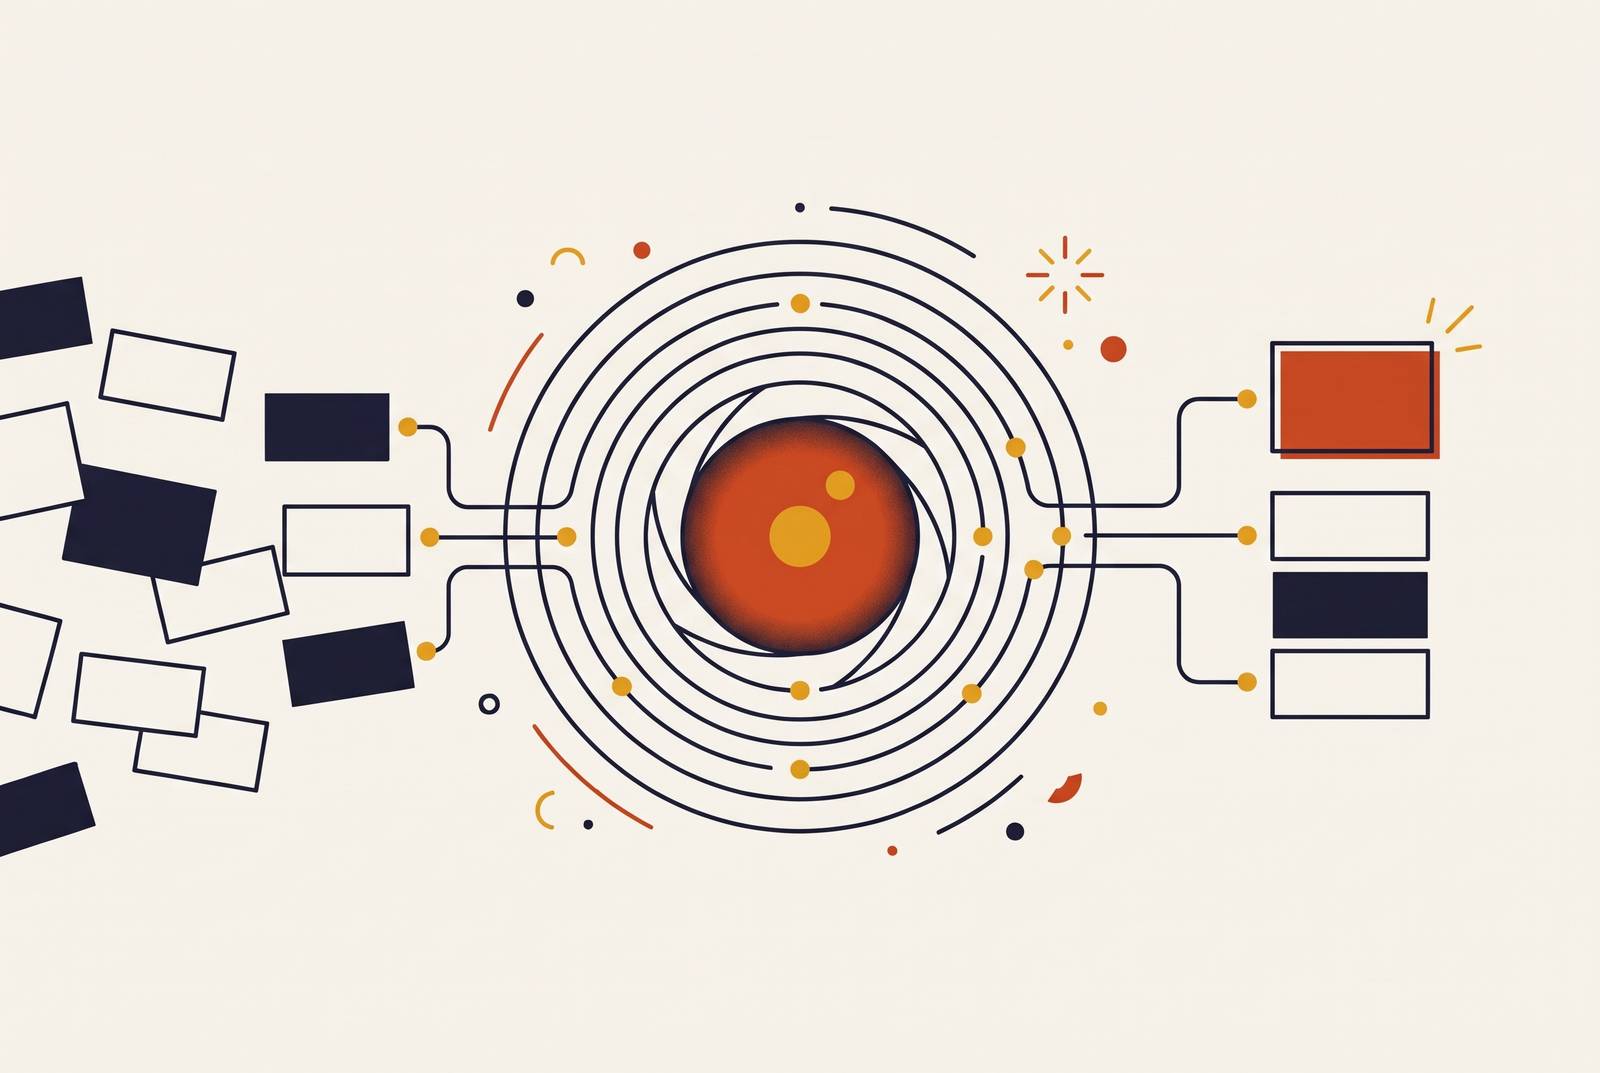
AI engines can fan out a query into sub-questions, then move through a four-step pipeline. They retrieve a pool of candidate sources, extract passages, score those passages, and cite only the few that score highest. Retrieval is only the first filter in this process. A page can enter the candidate pool without supplying any part of the answer the user gets. For the business, the gap that matters is between what the engine can use and what it chooses.
That gap grows as search becomes an answer interface. ChatGPT, Google AI Overviews, Perplexity, and Gemini are handling more customer queries directly, while over 65% of Google searches already end without a click as of 2026. Discovery can now happen without a website visit. Content teams are consequently competing for inclusion in a response that may satisfy the buyer before any source page opens.
Why ranking and citation are different goals requiring different strategies
Traditional ranking signals, including domain authority, backlinks, and keyword relevance, help a page enter the retrieval pool. They do not ensure the extraction and attribution of a particular passage. Ranking concerns a page’s position among competing results, while citation concerns its contribution to a generated answer. Ranking and citation require separate performance measures. Optimizing for access to the candidate pool does not automatically make the content useful at the point of selection.
The citation pattern makes that distinction concrete. A meaningful share of AI Overview citations come from pages outside the top ten for the query, and 31% rank nowhere in the top hundred. A well-ranked page can remain uncited, while a less prominent page with an extractable passage can be cited repeatedly.
This does not make SEO obsolete. Technical access and search relevance still help content become eligible, but eligibility serves a different purpose from extraction. The strategic objective moves beyond attracting a visitor to making a precise piece of information reusable in an answer. That changes what a content brief must specify and what a completed page must accomplish.
How AI engines decide which sources to trust and which passages to extract
AI engines assess source authority through corroboration and verifiability. A claim becomes safer to reuse when it aligns with reliable independent sources and remains consistent across contexts. Links alone do not provide that assurance. In this setting, E-E-A-T functions less as a gradual advantage than as a credibility threshold, with 96% of AI Overview citations coming from sources that pass E-E-A-T thresholds. Content that fails that test can remain outside the citation layer despite being retrievable.
The major platforms apply these principles differently. Google AI Overviews use the traditional ranking machinery and rely heavily on credibility signals and structured data. Perplexity performs live retrieval for each query, giving weight to currency and topical depth, while ChatGPT first depends on crawler access and then emphasizes credibility and concreteness. Their source selections overlap only a fraction of the time. A page’s success in one engine therefore does not establish its visibility in another.
Freshness adds another selection pressure because AI assistants preferentially cite fresher content than standard organic results do. Currency strengthens the usefulness of information that can already be trusted and extracted. The engine’s task is not simply to find a relevant page, but to select a passage that can answer the question without introducing error.
What content structure has to look like to be extractable
The production response is to make each answerable unit independently useful. A section should begin with a short, direct answer, then provide the detail needed to support it. If its meaning depends on an earlier explanation, or if the essential claim appears only after a long introduction, the engine has less usable material at the point of extraction.
That requirement changes the brief from a page topic into a set of answerable questions. Instead of commissioning a broad page about a subject, a team should identify the sub-questions an engine may fan out to and build a discrete answer unit for each. This production model sets out which questions get clear answers and which facts need to sit near those answers to make them useful. The page remains the container, but the passage becomes the working unit.
Structured answer blocks and schema that mirrors visible text help make those units legible. A niche blog that opens with a direct, structured answer can outperform an institutional source that buries the same information in a PDF or behind navigation layers. New production effort should therefore concentrate on the distinction between whether a page can be considered and whether anything on it can be lifted into an answer.
Why vendor-authored content is systematically under-cited by AI engines
Even well-structured answers face a separate obstacle when the brand is their only source. Leading AI platforms cross-reference independent domains for consensus, which disadvantages a publishing model in which a company’s blog supplies most of the evidence about that company. More polished prose does not create independent corroboration, and more pages on the same domain do not resolve the underlying trust problem.
A consumer app team illustrated the limit when it doubled publishing volume but continued to lose citations to Reddit threads and a Wikipedia category page. No single blog post offered a short, quotable, independently corroborated answer. The case exposes the weakness of treating publishing volume as a proxy for visibility when the selection process requires both extractability and outside support.
More is at stake than being seen, because AI answers shape what buyers think of a brand before they visit its site. Inaccurate or inconsistent descriptions can erode trust, while AI-referred buyers tend to arrive more qualified because relevance and credibility have already been filtered. Google’s enforcement posture reinforces the distinction between production and quality by targeting unverified, unedited content published at scale, rather than AI-assisted content that is edited, verified, and attributed. A brand still needs a website, but independent sources must also describe it in places the engines trust.
How third-party publication has become the primary channel for AI-driven brand discovery
Independent coverage supplies the corroboration that self-referential publishing lacks. Third-party editorial citations, review platforms, and aggregator appearances give Google AI Overviews evidence beyond the brand’s own claims, while Perplexity’s live retrieval rewards breadth of independent coverage across domains. Aggregators and niche publications help because information appearing next to other trusted sources can be validated and reused with greater confidence.
The HubSpot CRM example shows how that mechanism changes the source of brand visibility. A search for “best free CRM for small business” returned an AI Overview citing Zapier because its third-party page supplied the answer used in that response, despite the strong owned content on HubSpot’s own site.
A title with its own name, domain, editorial identity, and voice, functioning as an independent trade outlet rather than a branded content property, is structurally more citable than a company blog. Its role is different from a brand’s source-of-record site. The value comes from trusted editorial coverage among a wider range of sources, and putting the same promotional claims under another masthead does not provide that.
What the measurement framework has to look like when citation replaces ranking as the primary goal
Teams must measure access, selection, visibility, and the effect on the business separately. Rank tracking, organic sessions, and click-through rate still describe useful outcomes, but they do not show how often a brand contributes to answers that end without a visit. A missing click is not necessarily missing value. HubSpot documents that brands cited in AI Overviews earn 35% more organic clicks than those not cited. Click totals alone cannot explain the citation visibility associated with that difference.
The new framework has four linked layers, starting with eligibility and extraction rate. Eligibility asks whether the page is technically able to be considered, while extraction rate asks whether passages are being pulled from it. Citation share then measures how often the brand appears in answers to relevant queries, and assisted conversion tracks the revenue that comes later from AI visibility. Each layer answers a different operational question. Together, they distinguish an access problem from an extraction problem and a visibility gain from a commercial result.
Citation share and “share of model,” meaning how often a brand is named in answers to category-level questions, become primary performance indicators. Branded search volume is a way to gauge later demand, while lead quality helps show how much the resulting visits are worth. HubSpot’s own data showed that leads from AEO converted at a much higher rate than those from other sources. Reports therefore need to link being seen in answers with later demand and account for differences in what visits are worth. Teams that report only clicks are measuring the receding tail of search.
What a content strategy built for AI citation actually looks like end-to-end
An integrated strategy begins with the technical foundations inherited from strong SEO. Indexable pages, crawlable architecture, strong internal linking, valid structured data, and topical authority form the eligibility layer. On top of them, briefs decompose head queries into fan-out sub-questions and assign a discrete answer unit to each. Production becomes the systematic creation of citable passages rather than the accumulation of pages around keywords.
Distribution gives those passages a credible setting. Owned media remains the authoritative source of record for brand facts, while editorial coverage, review platform entries, aggregator appearances, and niche trade publications provide independent accounts of the brand. When brand descriptions, category claims, and differentiators stay the same across these sources, engines can cross-reference the information.
Accountability then follows the same path as discovery, from technical eligibility through extraction and citation to assisted conversion. This makes it possible to judge content by the job it performs rather than only by the traffic arriving at its address. The strategy is search-first underneath and answer-first in use. Its defining asset is a body of precise, extractable answers supported by independent sources that consistently describe the brand. Visibility emerges when that evidence becomes useful enough for an engine to include in the buyer’s answer.