Why AI Engines Treat Independent Domains as More Trustworthy
Independent corroboration across unrelated sources now outweighs a brand's own marketing claims.
AI engines treat independent domains as more trustworthy because they learned a hierarchy of sources from the open web. That distinction explains why strong on-page optimization cannot substitute for independent corroboration. For brands seeking discovery through AI answers, the decisive asset is a consistent record across unrelated sources.
Why AI citation behavior is a training artifact, not a design choice
A product manager at a mid-market SaaS company asks an AI assistant for the best project management tools for distributed engineering teams. The answer names three vendors and gives links. A fourth vendor with similar capabilities and a strong customer base is absent from the answer. It has been left outside the answer from which the buyer begins evaluating options.
The foundational explanation is a pattern absorbed during pretraining. On the open web, editorial publications, community forums, and review platforms supplied an authoritative record, while brand sites largely represented their own commercial interests. Models learned from that mix, including the repeated signs of editorial independence and agreement among publishers with no ties to each other. Schema and keyword density can change a page, but cannot rewrite that learned hierarchy.
Engines cite brand-owned pages to answer questions about pricing, features, and first-party specifications. Comparative questions require a different kind of evidence, because a vendor's account of its own strengths cannot establish its standing against alternatives. A claim backed by three independent publications carries more weight than one made by the vendor alone.
How the corroboration mechanism actually works inside retrieval
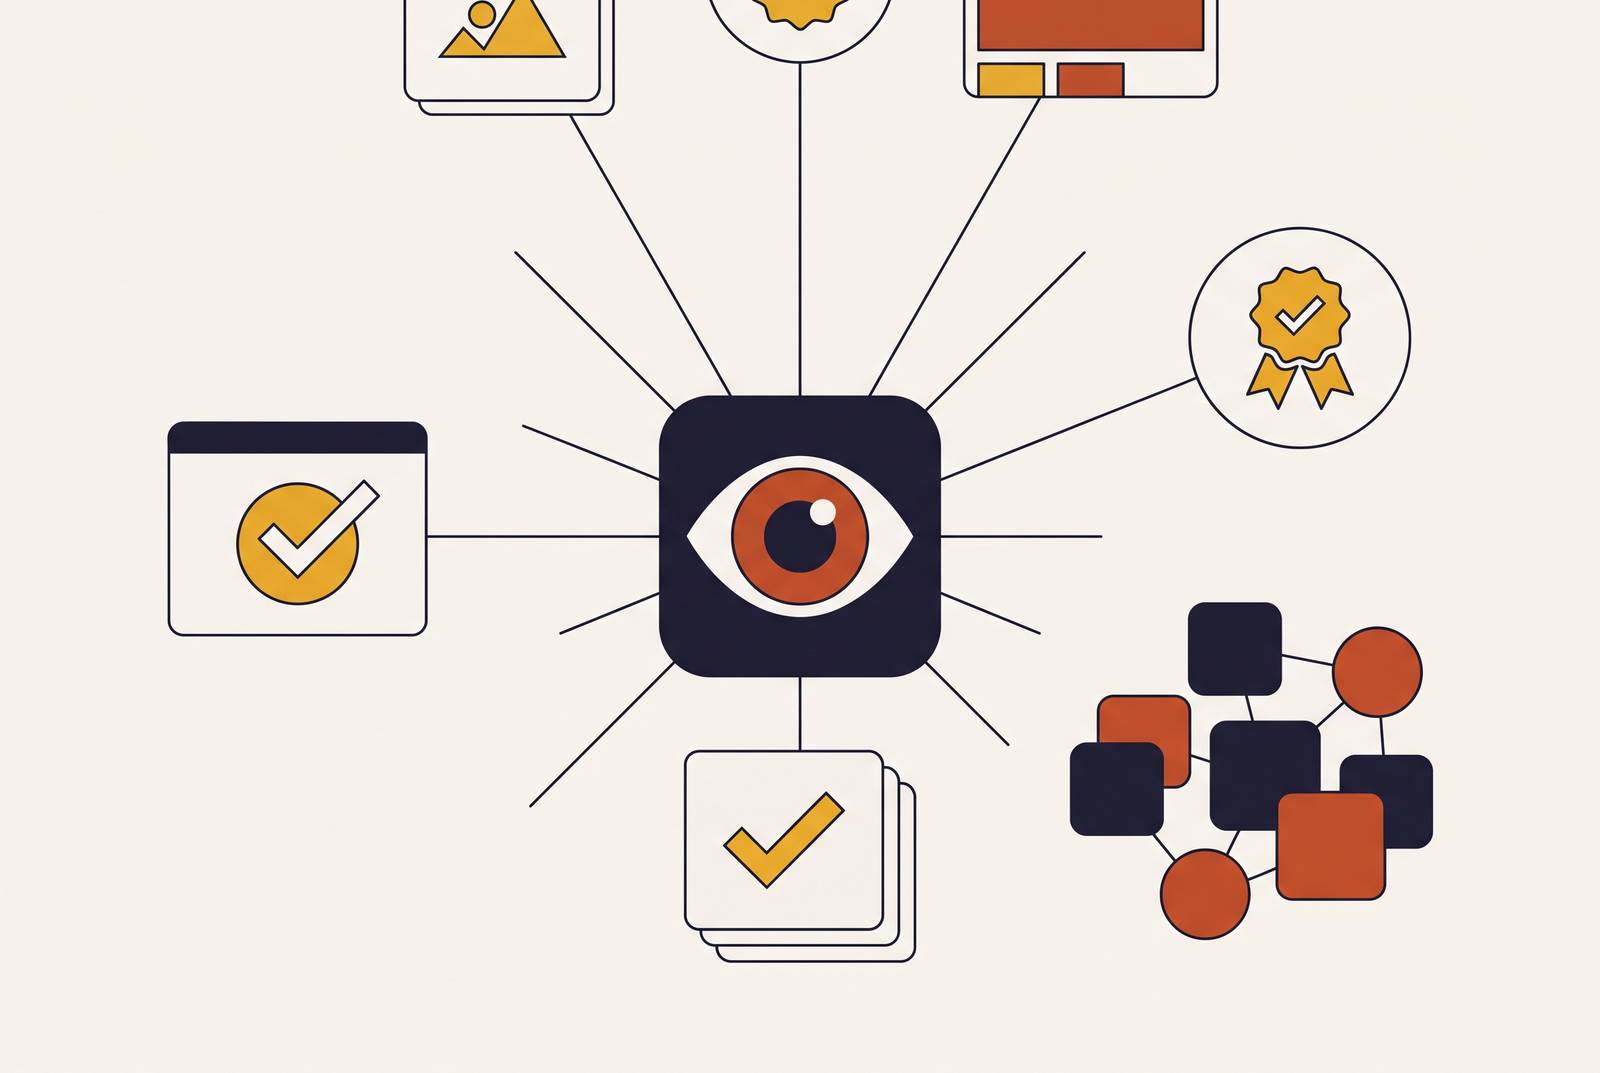
Corroboration is the mechanism that turns this hierarchy into a retrieval advantage. A claim found on one domain is an assertion, while agreement across unrelated publishers gives a retrieval system grounds to treat it as supported. Five properties help explain which page earns a citation role, namely corroboration, perceived independence, aggregation, freshness, and crawlability and licensing. These properties concern the evidence surrounding a page as much as the page itself.
Corroboration checks whether other sources back the same claim. Perceived independence asks whether those sources have an obvious commercial reason to make it. A vendor's self-description is weak evidence for a comparative answer because citing it as neutral judgment would effectively turn advertising into advice. Aggregation adds another advantage for independent sources. A review category page or community thread can contain many opinions about many products, matching the scope of a comparison in a way that one vendor's page cannot.
Freshness gives review platforms and community discussions an edge because they change more often than vendor sites. For a query about the best tool in 2026, recent activity supplies evidence of current relevance. Retrieving that evidence at scale requires crawlability and licensing. Google's expanded Reddit partnership, announced February 22, 2024, and OpenAI's similar partnership in May 2024 give Reddit advantages in access that an ordinary B2B vendor website cannot get.
Liu et al., 2025 found that isolated changes, including added statistics, authority language, and fluency improvements, were insufficient to reliably increase citation visibility and could disrupt the writing patterns models preferred to cite. The finding makes clarity an inadequate substitute for corroboration.
The entity chain: how AI engines build a confidence score for a brand
The entity chain makes cross-domain credibility concrete. It is an audit representation of how a brand, person, product, claim, and category are evidenced across owned and independent surfaces. Rather than evaluating a brand page alone, retrieval systems build an entity graph from crawled sources that mention the brand. When descriptions agree across non-affiliated domains, the system can have more confidence in its representation.
Each independent mention adds a node to that evidence graph. When different sources name the same product, place it in the same category, and describe consistent attributes, they supply distributed proof. Source diversity matters more than repetition within one publication because it provides separate grounds for confidence. A large concentration of mentions on one domain cannot supply the same independence. The structure of the record matters more than its sheer size.
This is not link-building under a new name. Links can connect references, but the mechanism at issue is confidence in an entity. A brand present only on its own domain has an entity chain of one, leaving little outside evidence for a retrieval system to use. Low confidence can lead the system to omit the brand or qualify its answer heavily.
What the citation studies show: independent mentions versus owned content
Ahrefs found that brand mentions across independent sources correlated 0.664 with AI Overview visibility, compared with 0.218 for backlinks. Independent mentions were roughly three times as predictive as the foundational authority signal of traditional SEO. That result supports the entity-chain argument, but it remains a correlation. That result alone cannot show that sharing a particular article more widely makes it more visible.
Stacker and Scrunch's December 2025 controlled study provides the strongest evidence in this brief because it tracked the same content across different publishing contexts. The study looked at eight articles, five AI platforms, and 944 prompt-platform combinations. Content published only by the brand had a low single-digit citation rate. In nearly one in five answers, systems cited the third-party version without citing the original brand piece. Holding the content constant makes the publishing source a more direct explanation of the gap than differences in copy quality.
A separate Stacker and Scrunch study examined dozens of stories and brands across thousands of prompts over a month. Publishing through earned media channels led to a median lift that nearly tripled AI search coverage across platforms. Brands with the smallest existing AI footprint gained the most. That finding suggests a current, specific story in credible publications can compete with a much larger established presence.
The controlled study also shows that a publisher can earn the citation while the originating brand receives no citation of its own. Using the same brand name across distributed content helps build parametric association as well as win retrieval citations.
How each major AI platform weights sources differently — and where vendor content lands in each
Platforms differ in how they apply this hierarchy. Source credibility, brand mentions, and explicit citations receive different treatment, so a brand can be visible in one sense and absent in another. For comparative discovery on ChatGPT and Perplexity, the central disadvantage remains that a vendor page offers self-description. The supplied evidence supports the distinction between first-party facts and comparative recommendations.
Claude places particular emphasis on E-E-A-T signals. Author credentials and organizational authority show a meaningful correlation with citation probability, making it especially selective about source credibility. Clear authorship and organizational standing help explain why two pages covering the same subject may not have the same citation prospects.
Gemini presents the strongest counterargument to a blanket claim that owned content has little value. It mentions brands in the large majority of appearances but cites sources only rarely. Yext's data shows that a majority of Gemini citations come from brand-owned websites with structured data. Owned-content investment therefore has a meaningful role on this platform. That exception supports maintaining structured data, but does not establish that a vendor blog becomes competitive for discovery queries on ChatGPT, Perplexity, or Claude.
Platform visibility is also unstable. SISTRIX found that a majority of domains cited in Google AI Mode answers changed from one week to the next, making entity-chain maintenance an ongoing task. Technical access creates a separate limit on that work. Amazon blocked 47 AI user agents in robots.txt, including OpenAI crawlers by January 2026, and its share of multi-category retail citations on ChatGPT dropped sharply. Walmart did not block those bots and overtook Amazon in ChatGPT citations, illustrating that crawlability is a prerequisite even for a prominent source.
Where buyers are migrating their trust — and why that accelerates the structural shift
Buyers are turning to the same kinds of sources that give retrieval systems independent evidence. TrustRadius's 2026 B2B Buying Disconnect Report found that a large majority of buyers read user reviews while deciding what to buy. A growing majority specifically visit software review sites, while reviews hosted on vendors' own sites account for a declining share of research. The distinction is not simply between marketing copy and customer testimony. Where that testimony appears also affects its role in the buying process.
Analyst reports have also suffered a dramatic decline in usage since 2022. That weakens the traditional authoritative third-party layer vendors once expected buyers to consult. Independent coverage still matters, but some independent sources do more than others to help buyers research a purchase. Where buyers do their research shapes which outside evidence they are likely to find. A vendor website paired with analyst validation now covers only part of how buyers find products.
Buyers also scrutinize AI answers rather than accepting them passively. A large majority fact-check in some form, and a meaningful share use the cited sources to verify an answer. For that path into a consideration set, appearing in the answer supplies the entry point and the citation supplies the next step. With nearly half of buyers saying they trust online resources less than before, perceived independence serves both machine retrieval and human judgment.
These behaviors create a reinforcing loop. Engines learned which signs to trust from independent sources, cite those sources, and send buyers to them. Buyers then give those publications further engagement and authority, which can reinforce their position in future training. The structural disadvantage of self-promotional content is therefore not merely a fixed inheritance from pretraining. Buyer distrust adds pressure in the same direction.
What the structural bias means for how brands should position content across independent publications
Third-party publication should be treated as discovery infrastructure rather than amplification after an owned-content campaign. The relevant sources earn trust in different ways, so appearing in them requires different work. Community threads on Reddit, Hacker News, and niche forums call for genuine participation. Review platforms including G2, Capterra, and TrustRadius require continuous customer review programs, because volume and recency matter together. Neither channel is well served by a one-off push.
Comparisons and “best of” listicles require publisher outreach to pages that already rank and receive citations. Documentation and technical references serve a different purpose, giving engines specifications. They remain an important owned surface because their content can answer factual questions directly. News and independent media depend on a real news hook, including funding, data, launches, or expert commentary.
Independent trade publications most closely match the editorial signals found in the training corpus. A publication with its own name, domain, and editorial voice occupies a different source role from a brand blog. The strategic value lies in credible editorial treatment across distinct domains. Ownership of another domain does not, by itself, establish the non-affiliation on which corroboration depends.
Owned content still needs to back that record by letting engines check claims made elsewhere. Pricing, specifications, documentation, and structured data have defined jobs within that verification layer. Discovery and verification are complementary, but they are not the same task. AI visibility depends less on how forcefully a brand describes itself than on how confidently unrelated sources establish what it is.