Structural Content Signals That Make an Article AI-Citable
Clear structure and fresh updates help AI systems extract and trust your claims for citation.
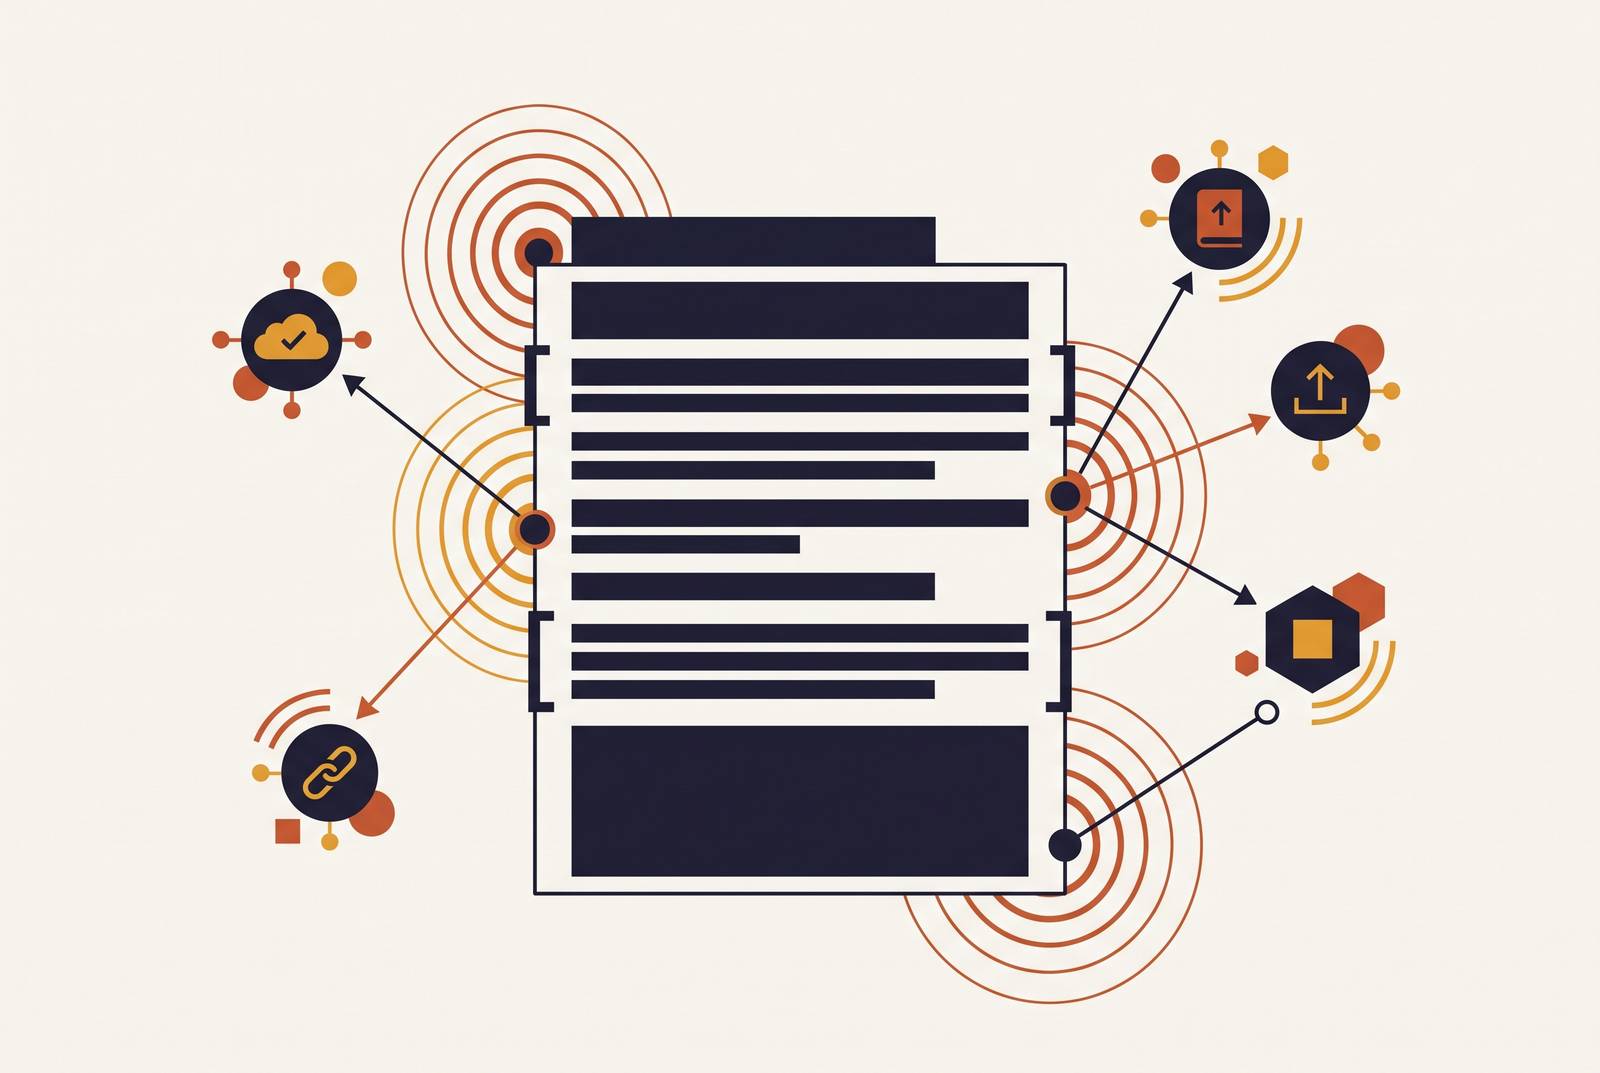
An article becomes AI-citable when its structure makes claims easy to extract, verify, and attribute. Direct answers, clear headings, current content, named sources, and accurate metadata all help, but they operate within a larger constraint. Source independence limits what on-page optimization can do, so an answer engine optimization strategy has to start with where the content is published.
How AI answer engines select which passages to cite
AI citation draws on passage-level retrieval, with more at stake than how popular a page is. During query interpretation, an engine identifies the concepts, entities, and relationships behind a question and retrieves candidate documents through conceptual similarity as well as keyword overlap. Retrieval and ranking then assess relevance, authority, recency, and structural quality. At the citation stage, the engine attributes particular claims to their sources. A page can enter the candidate set even if none of its passages earns attribution.
The decisive unit is a self-contained, verifiable claim. A sentence tied to a named source, date, or concrete figure gives the engine something specific to repeat and attribute. Even well-written prose gives the engine less to work with when its claims have no basis that can be checked. When extraction happens at the passage level, each choice about structure helps the engine find an answer it can use or makes that task harder.
Why answer placement in the first portion of an article disproportionately drives citation
An answer placed early in an article is easier to find and extract than one delayed by introductory material. Position is therefore a structural signal. Retrieval favors a short passage that answers the question without the engine having to read the argument around it. An opening that establishes context but withholds the conclusion makes that task harder.
Definition blocks and short-version sections serve this purpose because they compress the answer into a passage that can stand alone. A short passage with an unclear subject still needs the text around it, while a full definition names the subject and says what point is being made. The same principle applies within each H2 section, which should open with its central claim. This lets a section remain intelligible when retrieved separately from the article.
Early placement still calls for evidence to back the claim. It gives that evidence a clear claim to support, making the article easier to follow as well as easier to extract. Placement answers where the answer belongs. Heading structure determines how the model navigates to the right place.
How sequential heading structure helps AI models navigate and extract content
A sequential heading hierarchy gives AI systems a machine-readable map of an article’s questions and answers. Its purpose is to establish the scope of each passage. An H2 identifies a primary question, while an H3 divides that question into answerable sub-claims. An H4 can label components within a sub-claim when that additional level is useful.
Specific headings make this hierarchy useful for retrieval. “How sequential heading structure helps AI models navigate” identifies what the passage below will explain, whereas “Structure” leaves that work to the surrounding text. A heading should therefore function as a standalone question or claim whose answer appears beneath it. This gives the engine both a retrieval anchor and a boundary for interpreting the passage.
Navigability, however, is not the same as trust. A model may locate the right passage and still pass it over if the content appears stale.
Why content freshness functions as a trust signal, not just a relevance filter
Freshness signals active editorial stewardship. AI systems treat recency as a proxy for reliability, so a well-structured answer can lose citation share to less-polished content that more clearly reflects the current topic. This matters because extraction alone does not establish that a claim is still useful. A passage must be both understandable in isolation and credible at the time of retrieval. Freshness addresses the second requirement.
Substantive updates provide stronger evidence of currency than cosmetic date changes. A new example, an updated figure, or a section answering a previously uncovered question changes what the page contributes. A quarterly refresh cadence gives teams a regular time to make those changes. Its purpose is to keep the answer current. A page that discusses a superseded tool or outdated practice can still appear stale despite a new dateModified value.
The distinction is between a declaration of freshness and visible evidence of it. Content supplies that evidence by reflecting the current state of the subject. Schema provides a parallel layer of metadata that some models read separately from the prose, but that layer cannot substitute for substantive maintenance.
What schema markup actually does — and does not do — for AI citation
Schema is a baseline for AI readability. Missing markup can create friction for parsers, but adding it does not give a page a material advantage over equally structured competitors that also use it. This sets the boundary of what schema can accomplish. It helps describe and organize content that exists. It does not supply the evidence or independence needed to support citation of a claim.
The relevant schema types serve distinct purposes. Article and BlogPosting establish authorship, publication date, and dateModified for freshness parsing. FAQPage organizes question-answer pairs, while HowTo fits content with steps that can each be cited. Person and Organization anchor the entities associated with the page. Their usefulness depends on their fit with the visible content.
That requirement makes schema a matter of accuracy as much as implementation. Markup for content that is missing from the page does not make a citation more likely and can lead to trust penalties. An explanation can still be out of date even with a recent dateModified value. Schema should reinforce what the reader can see, including the author, the subject, and the actual content format. Once that foundation is in place, named entities and evidence deserve more attention than further metadata refinement.
How named-entity density and E-E-A-T signals build the credibility layer AI systems assess
Named entities give a well-structured page concrete referents that an AI system can carry into an answer. Specific people, organizations, studies, dates, and products make claims less dependent on vague description. A passage anchored in those entities gives the model a clearer account of what is being asserted and what supports it. This is the semantic credibility layer that formatting alone cannot provide. A fresh, navigable page can still lose citations when another source offers more verifiable substance.
Writers and editors control much of this layer through attribution. An author byline with verifiable credentials identifies who stands behind the explanation. Named experts whose qualifications are given offer more support than broad claims about what people in the industry think. Sources and studies cited in the text tie its claims to evidence from outside the page. These elements support E-E-A-T by making expertise and accountability visible.
Documented observations from direct use, testing, or field work can also provide experience signals. Their value lies in the evidence they contribute. Entity density also helps when names make claims clearer, but a list of names detached from the argument adds little. Even a page with an expert byline and named sources has not resolved every trust question. Entity signals establish what the page knows and who supports it, while source independence addresses whether the publisher has a reason to be biased.
Why source independence is the structural signal that vendor-authored content cannot replicate
An editorially independent publication and a brand’s own domain have different places in the AI citation hierarchy. Better formatting does not erase that distinction because it does not change the publisher’s relationship to the subject. A vendor-authored page can be correct, useful, and well sourced while still speaking for a party with a stake in the subject. Independence is therefore a property of the source context.
This explains why strong execution can coexist with limited citation from an owned domain. A brand may have direct answers, sequential headings, current content, accurate schema, and expert attribution, yet its domain may still supply only a minority of the AI citations mentioning its name. The missing signal may be the external reputation established through third-party editorial coverage. That distinction prevents teams from treating every citation gap as a formatting problem.
AI engines more often filter out content that clearly promotes something, and paid placements rarely have the trust signals of earned coverage. Moving a promotional claim onto another site does not necessarily confer editorial independence. Teams must therefore consider not simply how to publish elsewhere, but how to place useful content within a genuinely independent source context.
How third-party publication raises the ceiling that on-page optimization alone cannot breach
Third-party publication places extractable content inside a source context that AI systems are more predisposed to trust. It is a distribution layer. The same on-page signals remain necessary, but an independent publisher changes the authority attached to them. This is how distribution can raise the ceiling that owned content reaches. The distinction concerns where the content appears and the editorial relationship that location represents.
Stacker and Scrunch tested eight articles published in two ways, only on brand domains and across third-party news publishers. Their test measured 944 prompt-and-platform combinations and found that the citation rate on third-party publishers reached 34%, compared with a substantially lower rate on brand domains alone. This is the strongest controlled evidence in the brief for the independence argument because it compares publication conditions for the same articles. It supports making source context part of the plan from the start, rather than leaving it to a final push to promote the content.
Publication architecture matters within that strategy. An independent trade publication with its own domain, name, editorial voice, and masthead carries independence signals that a brand subdomain or co-branded byline does not fully inherit. Presence across multiple independent sources can increase how often a brand appears in AI responses beyond a simple additive effect.
Putting the signals together: an operational checklist for AI-citable content
Tier 1 is source context because it offers the highest leverage and cannot be replaced by work on the page. Establish or secure placement in independent third-party publications on their own domains. Seek earned editorial coverage from major industry publications, research institutions, and established analyst outlets. Audit community and forum presence, including Reddit, niche forums, and Substack newsletters, as potential citation channels as well as referral sources. For resource-constrained teams, this tier addresses the constraint that better formatting cannot solve.
Tier 2 is document architecture, including the passages that architecture makes available for extraction. Open each page and section with a direct answer, then organize the explanation through a sequential H2 > H3 > H4 hierarchy as needed. Make every heading a specific question or claim, and use definition blocks or short-version summaries where complex topics need a self-contained answer. Establish a quarterly refresh cadence that produces substantive updates. These steps make the content findable, extractable, and visibly current.
Tier 3 is semantic credibility. Anchor claims in specific people, organizations, studies, and dates where those details provide evidence. Include expert attribution with stated credentials, and cite external sources to support assertions. Tier 4 is schema and metadata hygiene. Apply Article, FAQPage, HowTo, and Person schema as appropriate, keep dateModified tied to actual changes, and make the markup reflect the visible page.
Track citation frequency and share of model across AI platforms as well as rankings and organic traffic. Executing the tiers without tracking citation leaves the central question unanswered. The signals are working only when the measurement shows that engines are finding, trusting, and attributing the content.